當您使用官方 Python SDK 時,建構 MCP 伺服器會變得簡單許多。您不需要手動撰寫複雜的 JSON schema,而是可以使用裝飾器(decorators)來定義工具,讓 SDK 處理繁重的工作。
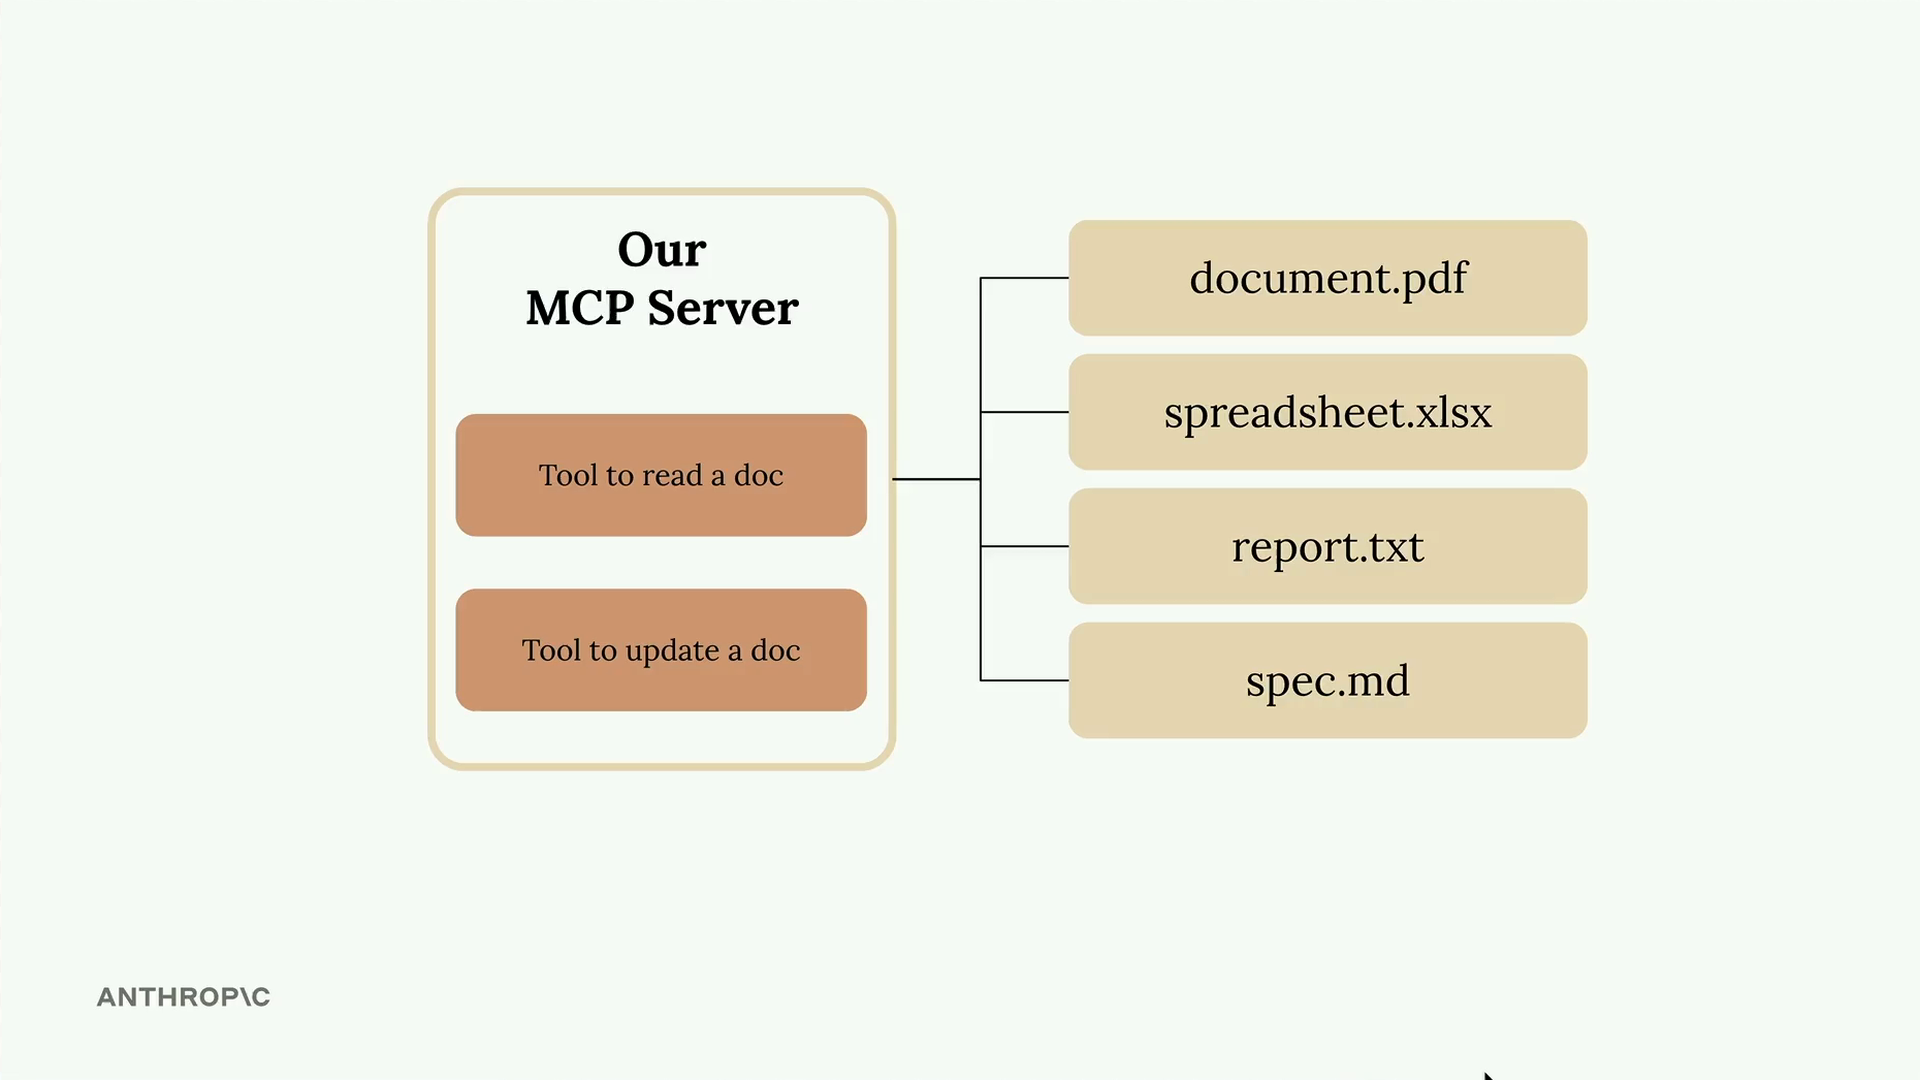
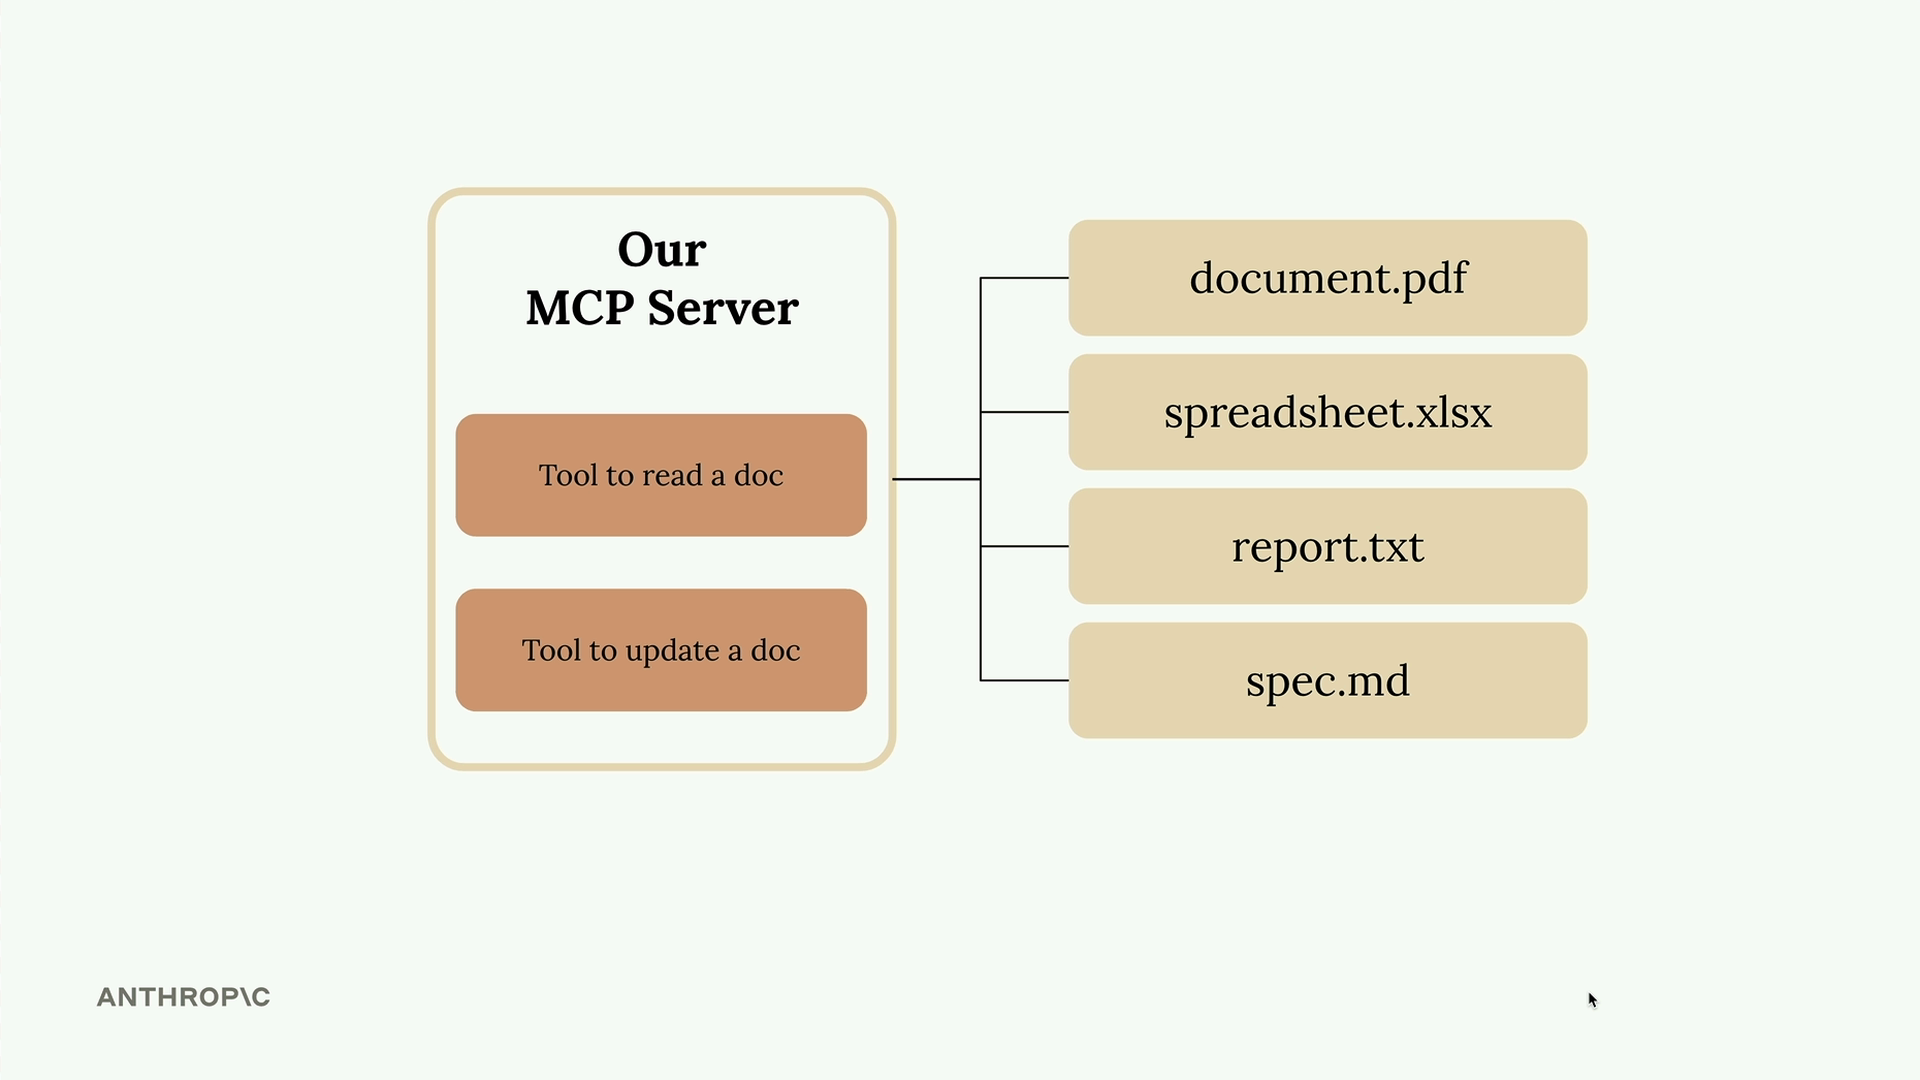
在這個範例中,我們正在建立一個具有兩個核心工具的文件管理伺服器:一個用於讀取文件,另一個用於更新文件。所有文件都以記憶體中的簡單字典形式存在,其中鍵是文件 ID,值是內容。
設定 MCP 伺服器
本專案使用 MCP Python SDK 的第 1 版,其設定會為您安裝該版本。如果您自行建立專案,請安裝 "mcp[cli]<2"。第 2 版將 FastMCP 重新命名為 MCPServer,因此下方的匯入在該版本上會失敗。
Python MCP SDK 讓伺服器建立變得簡單直接。您只需一行程式碼即可初始化伺服器:
from mcp.server.fastmcp import FastMCP
from pydantic import Field

mcp = FastMCP("DocumentMCP", log_level="ERROR")
這會建立一個功能完整的 MCP 伺服器,能夠處理工具定義、客戶端連線以及訊息路由。
使用裝飾器定義工具
SDK 的裝飾器方法消除了手動撰寫 JSON schema 的需求。以下是如何定義一個簡單的工具:
@mcp.tool(
    name="add_ints",
    description="Add two integers together",
)
def tool_fn(
    a=Field(description="First number to add"),
    b=Field(description="Second number to add"),
) -> int:
    return a + b
在幕後,MCP 會產生 Claude 需要理解的完整工具 schema,以知道何時以及如何使用您的工具。
建構文件讀取工具
第一個工具根據 ID 讀取文件內容。它接收一個文件識別碼,並從我們記憶體中的字典傳回對應的內容:
@mcp.tool(
    name="read_doc_contents",
    description="Read the contents of a document and return it as a string."
)
def read_document(
    doc_id: str = Field(description="Id of the document to read")
):
    if doc_id not in docs:
        raise ValueError(f"Doc with id {doc_id} not found")

    return docs[doc_id]
此函式包含基本的錯誤處理,以捕捉對不存在文件的請求。當 Claude 以有效的文件 ID 呼叫此工具時,它會以字串形式接收到完整的文件內容。
建立文件編輯工具
第二個工具對文件執行簡單的尋找與取代操作。它需要三個參數:文件 ID、要尋找的文字,以及取代文字:
@mcp.tool(
    name="edit_document",
    description="Edit a document by replacing a string in the documents content with a new string."
)
def edit_document(
    doc_id: str = Field(description="Id of the document that will be edited"),
    old_str: str = Field(description="The text to replace. Must match exactly, including white space."),
    new_str: str = Field(description="The new text to insert in place of the old text.")
):
    if doc_id not in docs:
        raise ValueError(f"Doc with id {doc_id} not found")

    docs[doc_id] = docs[doc_id].replace(old_str, new_str)
此實作使用 Python 內建的字串取代(replace)方法,該方法需要完全相符(包括空白字元)。此工具會就地修改字典中的文件。
SDK 方法的主要優點
- 不需要手動撰寫 JSON schema
- 類型提示(type hints)提供自動參數驗證
- 欄位描述有助於 Claude 理解工具用途
- 錯誤處理能與 Python 例外自然整合
- 工具註冊透過裝飾器自動完成
MCP Python SDK 將工具建立從複雜的 schema 撰寫工作轉變為直接的 Python 函式定義。您的工具變得更易於維護且更容易測試,同時 Claude 也能獲得有效使用這些工具所需的所有元資料。